

d-Matrix® Corsair™ Redefines Performance and Efficiency for AI Inference at Scale
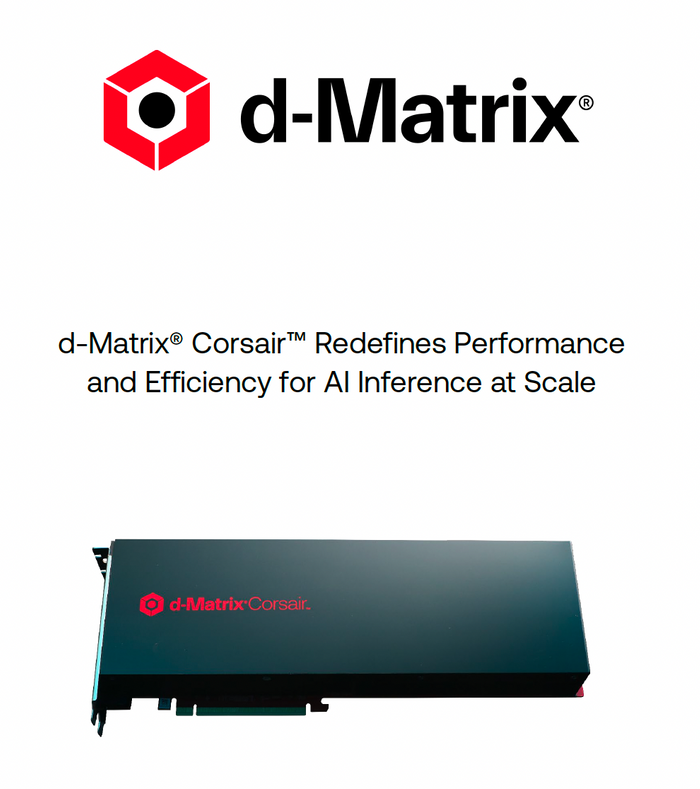
AI inference is increasingly constrained by memory bandwidth, latency, power, and cost. This white paper explores how d-Matrix Corsair™ takes a fundamentally different approach to these challenges with a purpose-built architecture for generative AI inference.
Learn how Corsair combines Digital In-Memory Compute (DIMC™), chiplet-based scaling, high-bandwidth integrated memory, advanced numerical formats, and the Aviator™ software stack to accelerate token generation and efficiently scale from PCIe cards to servers and racks. The paper also examines latency-bound inference and compares Corsair performance with GPU-based infrastructure across leading LLM workloads.
Download the white paper to see how a memory-centric, inference-first architecture can change the performance and economics of AI inference at scale.