-
Agentic AI creates thousands of latency-sensitive interactions, changing network traffic patterns and placing greater demands on AI infrastructure.
-
Inference efficiency increasingly depends on both overall throughput and delivering responsive token generation to individual users at a sustainable cost.
-
As accelerator clusters grow, the network fabric connecting them is becoming a major performance bottleneck.
-
Traditional copper connections face limits in reach, power, and signal quality, while co-packaged optics can connect larger accelerator domains across multiple racks with lower energy use.
-
Scaling co-packaged optics will require an open ecosystem across photonics, chips, packaging, and racks, alongside mature manufacturing, testing, supply chains, and reliability standards.

Vivek Gupta, CSO, Ayar Labs

Daniel Morris, Member of Technical Staff, OpenAI; Hokyoon Lee, Director of DRAM Solution Engineering, Samsung; Vidhya Thyagarajan, Head of AI SOC Architecture, Intel and Steven Woo, Fellow & Distinguished Inventor, Rambus
-
New chip-bonding techniques can shorten data paths and increase memory density, improving HBM performance while reducing the energy needed to move data.
-
Z-HBM aims to reduce power consumption and thermal resistance, but requires close co-design with XPUs to account for different architectures, space constraints, and thermal profiles.
-
Z-NAND targets local AI systems where privacy and strong on-device performance are priorities.
-
By combining advanced stacking and connectivity, Z-NAND aims to deliver higher bandwidth, lower latency, and lower power at a cost closer to NAND than traditional high-performance memory.
-
As agentic AI increases reliability requirements, protections such as error correction, data scrubbing, snapshots, and migration are essential to prevent silent data corruption.
-
As AI models and context windows grow, infrastructure needs flexible hardware, large memory capacity, and networks designed around increasingly powerful rack-scale systems.
-
DPUs can help secure, manage, and monitor traffic entering AI clusters, while making network optimization more programmable.
-
Training traffic is relatively predictable and schedulable, while inference traffic is more dynamic and creates harder-to-manage congestion.
-
Traditional passive networks can leave GPUs waiting for data, reducing utilization and wasting expensive compute capacity.
-
Active, in-network computing can process workloads as data moves through the network, improving GPU utilization and potentially delivering significant gains in both training and inference performance.
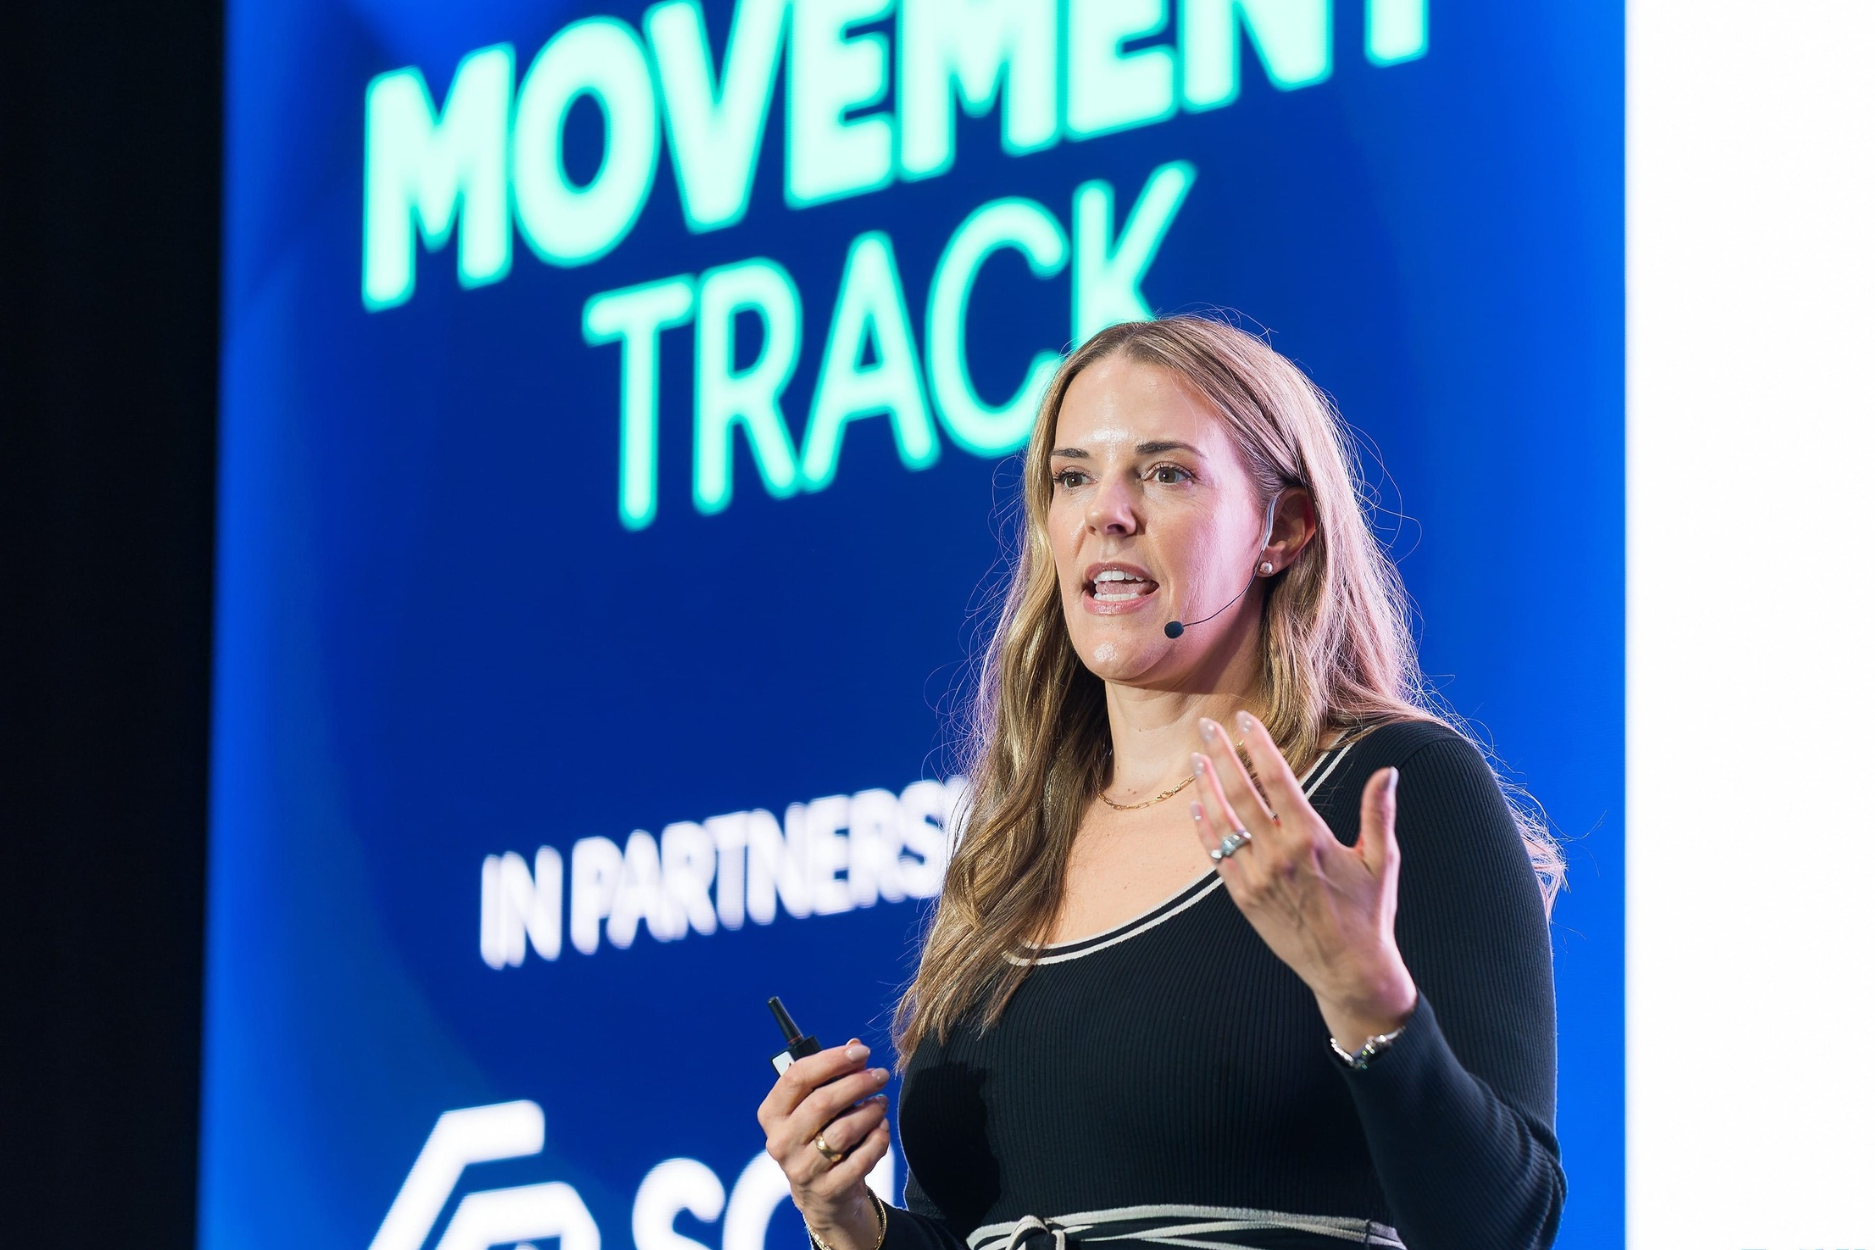 Lisa Spelman, CEO, Cornelis Networks

Vivek Sarathy, VP, Product, iPronics; Albert Chen, Director of Applications Engineering & Solutions Architecture, Amphenol; Deepti Chandra, VP, Product & Marketing, Upscale AI; Nandan Nayampally, CCO, Baya Systems and Kurtis Bowman, UALink Consortium Board Chair & Director of Architecture and Strategy, AMD
-
Scale-up networks need to connect growing numbers of GPUs efficiently while supporting a mix of hardware and increasingly diverse AI workloads.
-
Programmable, workload-aware networks can adapt routing in real time for the different requirements of training, inference, and agentic AI.
-
Training prioritizes high bandwidth, while inference places greater emphasis on predictable latency and efficiently allocating resources between prefill and token generation.
-
Increasing system density requires networking to be designed alongside power, cooling, mechanical systems, interconnects, and serviceability.
-
Copper remains effective for shorter connections, while optical networking becomes increasingly important at higher bandwidths and densities, with open standards helping different technologies work together.
-
AI’s memory challenge now extends beyond bandwidth to include capacity, latency, power, cost, and the growing expense of moving data.
-
Inference adds further pressure as systems need to retain user context and other state, making it more efficient to store and reuse information than repeatedly recompute it.
-
Techniques such as improved attention mechanisms, lower precision, and pruning can reduce KV-cache memory requirements.
-
Efficient inference requires model weights and KV caches to be intelligently distributed across different memory tiers, as scaling HBM alone faces cost, power, and thermal limits.
-
Closer hardware-software co-design, including technologies such as 3D integration, photonic fabrics, and pooled memory, could expand capacity while reducing costly data movement.

Vinay Gangadhar, Principal AI Hardware Architect, Microsoft; Andy Mills, VP, Advanced Product Development, Penguin Solutions; Nuwan Jayasena, Fellow, AMD, Karthik Ganesan, Technical Fellow, Micron and Debendra Das Sharma, Board Chair, CXL Consortium