- As AI clusters span multiple buildings, network design must account for distance, latency and the weakest links.
-
High-bandwidth, redundant networks help contain packet loss and prevent individual failures from disrupting training.
-
Purpose-built tent data centres can meet cluster requirements while reducing deployment times by 70–80%.
-
At this scale, component failures are inevitable, making detection, failover and coordination across cooling, facilities and hardware essential.
-
PATH software aligns model workloads with the physical cluster to improve availability, cost and recovery, while keeping the focus on user and business outcomes.

Santosh Janardhan, Head of Infrastructure, Meta
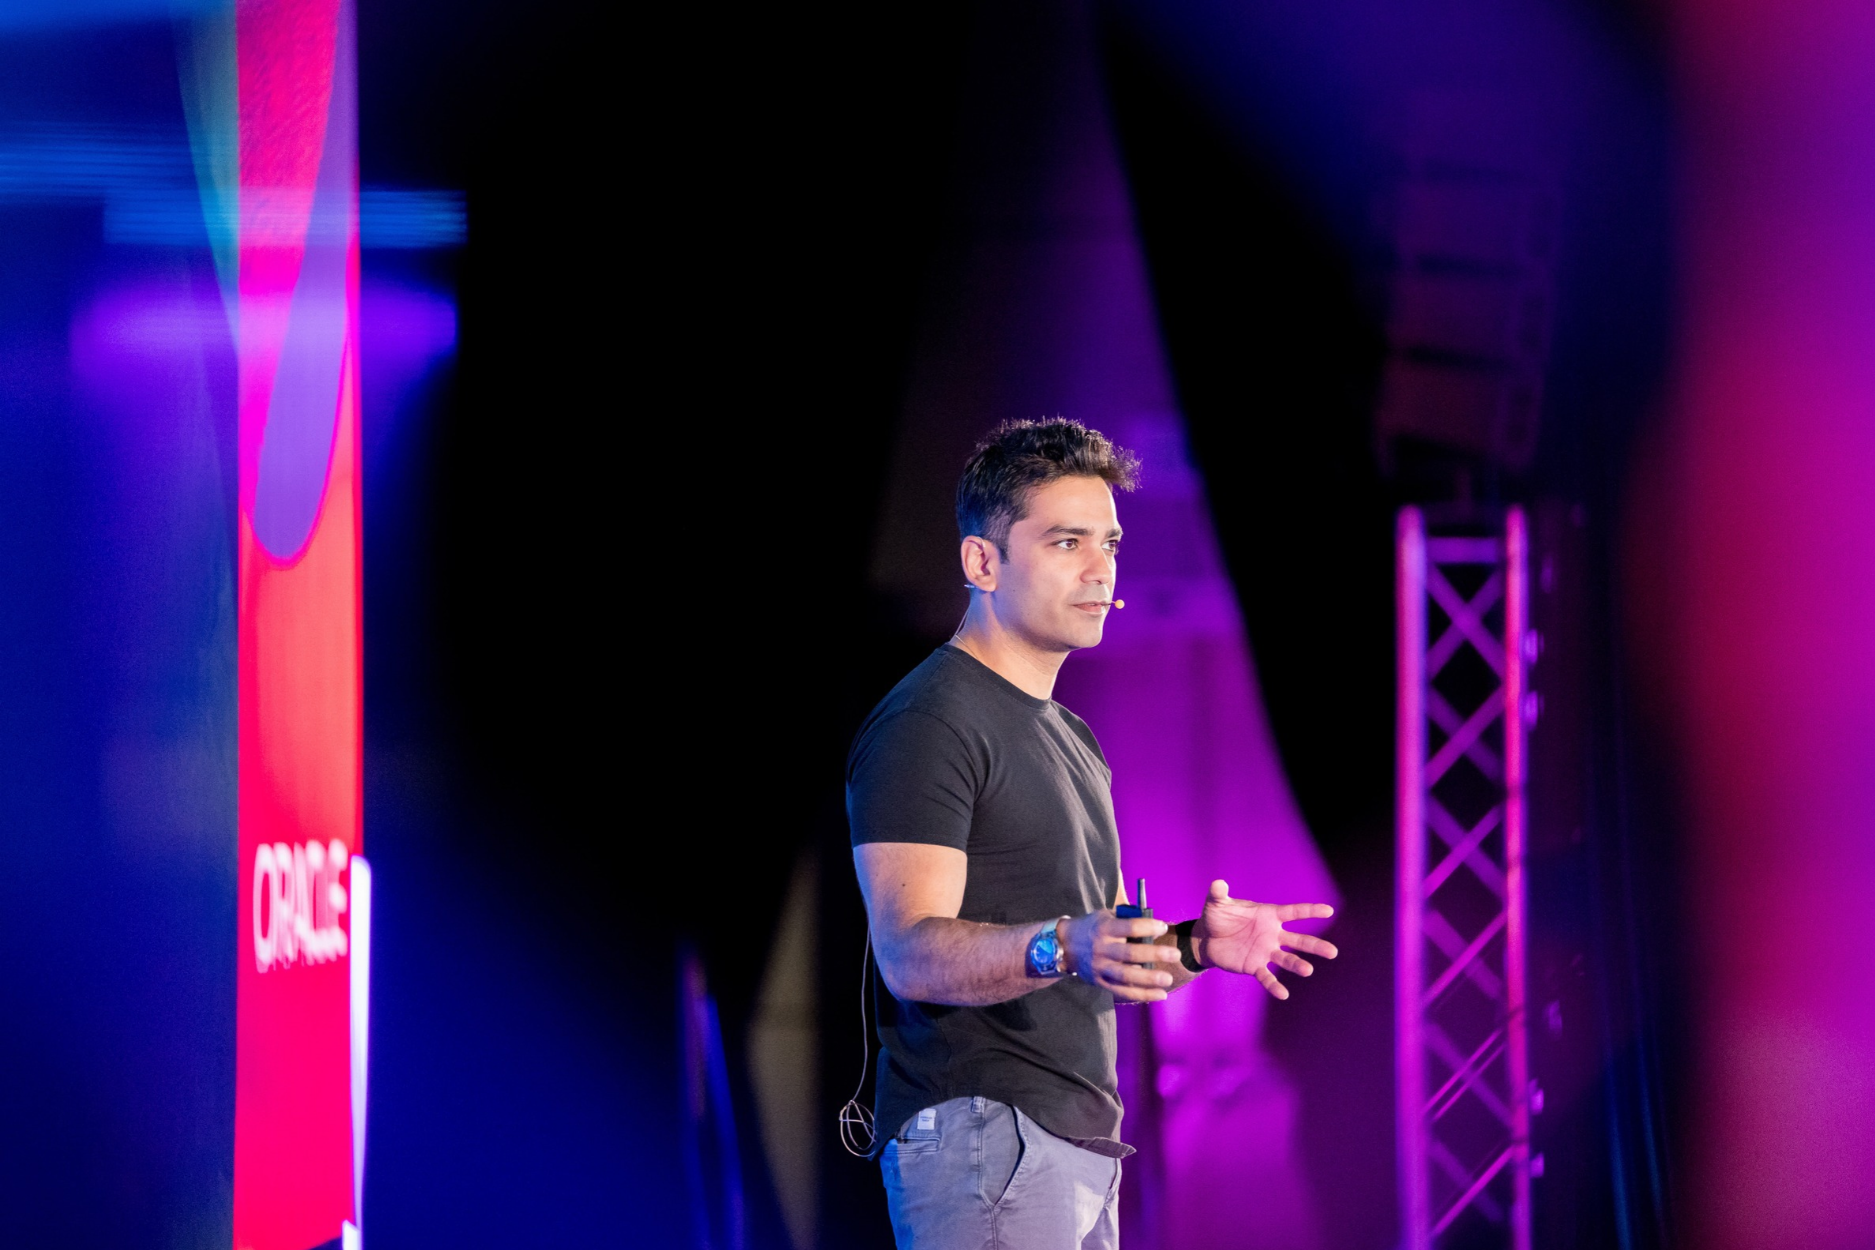
Karan Batta, SVP, Oracle Cloud Infrastructure, Oracle
-
Scaling AI requires more than buying GPUs: data centres, power, cooling and deployment capacity must all come together.
-
OCI offers a range of NVIDIA GPUs and accelerators for workloads from smaller tasks to large-scale training, with consistent capabilities across its region models.
-
OCI Acceleron combines host acceleration, direct data paths and a resilient, multi-planar network to improve GPU utilisation and keep training jobs running through failures.
-
Supporting OpenAI’s model roadmap depends on OCI delivering usable capacity and optimising the full infrastructure stack.
-
Supply chains, construction timelines and capital requirements shape how quickly planned capacity can be delivered to customers.
-
Moore’s Law and traditional power scaling have slowed, pushing chipmakers towards specialised AI accelerators and new architectures.
-
Memory capacity has not kept pace with compute, making it a major bottleneck even as HBM improves bandwidth.
-
AI’s tolerance for approximation has driven rapid progress in lower-precision computing, reducing the resources needed for many workloads.
-
Better chips alone cannot transform performance: models, software, networking and rack-scale systems need to be designed together, despite how quickly AI models change.
-
Reducing AI’s carbon footprint requires decisions across the full stack, from model design and hardware to data centre efficiency and where electricity is sourced.
 Dave Patterson, Distinguished Engineer & Google Fellow, Google and Ian Cutress, CEO & Chief Analyst, More than Moore

Dylan Patel, Founder, CEO & Chief Analyst, SemiAnalysis and Peter DeSantis, SVP, Foundational AI Models, Custom Silicon & Quantum Computing, Amazon
-
AWS’s Nitro offloads virtualisation to dedicated hardware, improving isolation and networking for demanding cloud workloads.
-
Broad deployment and accessible software matter as much as chip design: PyTorch support, profiling tools and open instructions help customers optimise Trainium workloads.
-
AWS adapted its accelerator roadmap as LLM requirements evolved, with Trainium’s memory bandwidth and cost positioned around token generation economics.
-
Custom silicon succeeds when it delivers performance, security and savings across the fleet, rather than leading on individual benchmarks.
-
Graviton uses insights from customer and AWS workloads to improve compute performance and cost efficiency.
-
Rapidly changing AI demand makes data centre capacity harder to forecast and calls for flexibility across hardware, power, land and building design.
-
Power and water constraints need to shape plans from the outset, with utilities involved early and load forecasts shared.
-
Staged investment lets developers expand as demand becomes clearer while managing capital risk.
-
Developers should be transparent with communities about power, water, jobs, taxes and local skills development.
-
Lasting projects depend on fair, long-term partnerships that use local resources responsibly and create economic value for surrounding communities.

Kevin Janda, CVP, Data Centers, Microsoft and Matt Kimball, VP & Principal Analyst, Moor Insights & Strategy